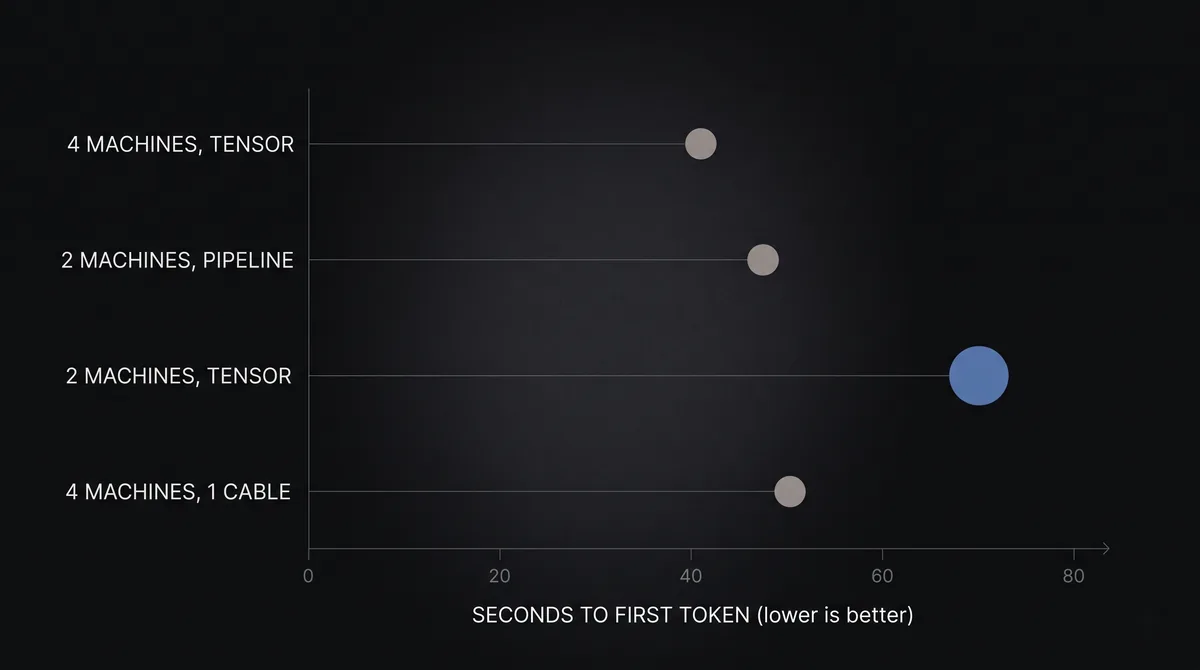
A dot plot of time-to-first-token across four hardware configurations, one point clearly worse than the rest

Apple's Best MLX Number Lives in a Tab a Fetcher Never Gets

Apple’s MLX post verifies on every load-bearing figure. Its best number sits in a table tab that is not server-rendered, so a fetcher-based reader never sees it. A full recount of all 32 parallelism cells.
October 16, 2026 · 5 min · 977 words
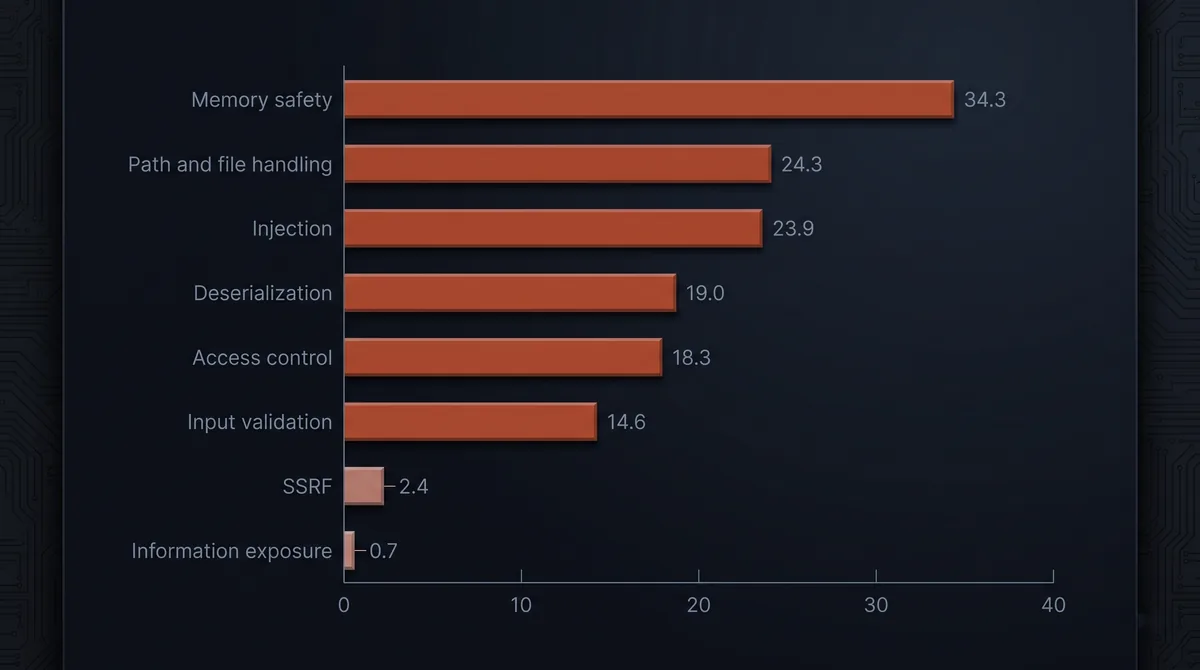
A horizontal bar chart of vulnerability categories, two short bars among several long ones

Three Fixes Work, Two Do Not, and SSRF Stays at 2.4%

An agent benchmark where the top performer on functional tests wrote the least secure code. Three interventions measurably help, two do not, and two weakness families stay near zero throughout.

October 15, 2026 · 7 min · 1480 words
A funnel of particles narrowing through rings, some breaking apart at the exit

CheckerBench: 78% Compiled, 32% Were Accepted

A new benchmark had AI agents write reusable static-analysis checkers. 78.25% compiled, 73.65% told the broken revision from the fixed one, 32.30% were accepted. The loss is almost entirely after detection, and the two obvious explanations both test small.

October 9, 2026 · 7 min · 1369 words
Two spheres of different size facing each other across a measuring scale whose gradations are crowded on one side and stretched on the other

Laya vs Jev: A Challenger With Its Own Scorecard

An open-source challenger to Jev ships with a comparison table. The accuracy claim does not survive reading the rest of the page, but the structural argument does.

September 28, 2026 · 4 min · 641 words
Four illuminated spheres on a baseline; the rightmost dissolves into particles beside a dashed line continuing into empty space

GPT-6 Sol and Luna: Reading the Benchmark Footnotes

OpenAI’s GPT-6 Sol and Luna announcement is a cost-efficiency pitch. Its own footnotes concede that the closest competitor’s cost is the one figure not reported.

September 24, 2026 · 5 min · 1023 words