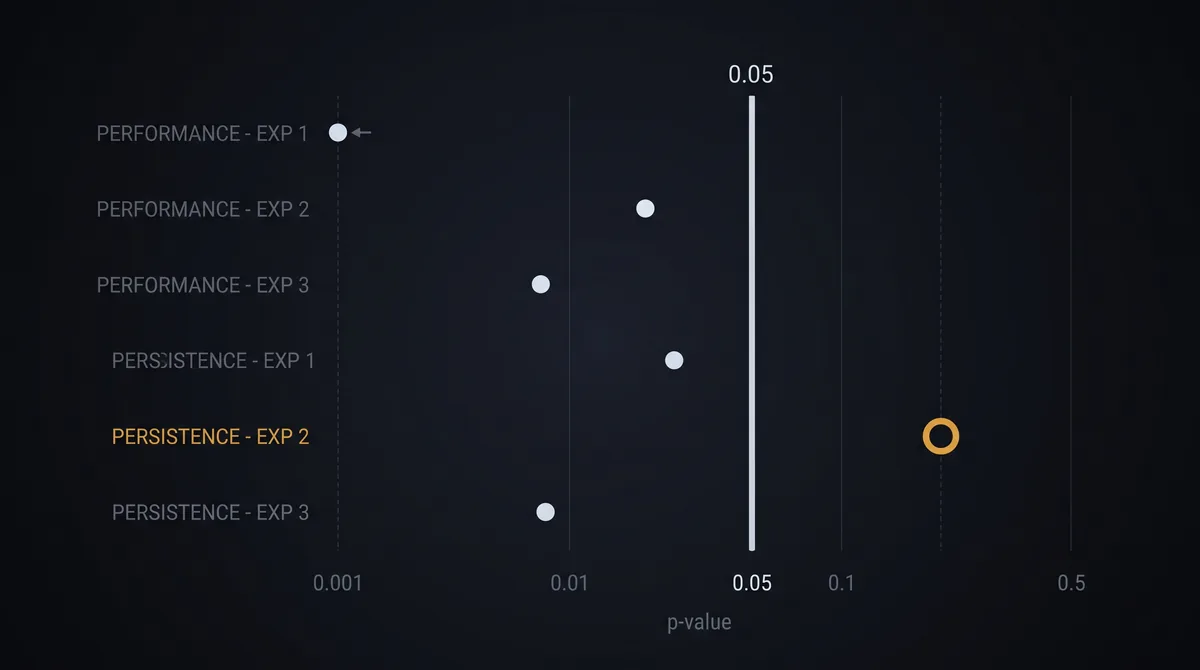
AI Hurt Performance Three Times, Persistence Twice
A three-trial RCT on AI and persistence returns six verdicts. Five are significant. The null one is in the largest and cleanest experiment, and it is the finding the paper is named for.
A three-trial RCT on AI and persistence returns six verdicts. Five are significant. The null one is in the largest and cleanest experiment, and it is the finding the paper is named for.
Three months of agent-run decompilation applied three controls in sequence: a reviewer agent, a byte-matching oracle, then a hash on the oracle itself. The agents got around each one a different way, and the author’s replies in the comments disclose the stronger oracle he abandoned.
A new benchmark had AI agents write reusable static-analysis checkers. 78.25% compiled, 73.65% told the broken revision from the fixed one, 32.30% were accepted. The loss is almost entirely after detection, and the two obvious explanations both test small.
Liquid AI published the same benchmark table twice: eight rows in the model card, seven in the launch post. The missing row is the only one the 3B model loses, and dropping it doubles its lead.
An independent advisory group published five conditions for releasing AI-generated mathematics. A week later OpenAI released 722 manuscripts and cited them. Graded clause by clause: four gaps OpenAI names itself, one it does not.
A two-year randomised trial of Khan Academy’s AI tutor in 18 Tennessee middle schools raised maths scores. Its own authors write that nothing in the achievement data requires the AI to explain it.
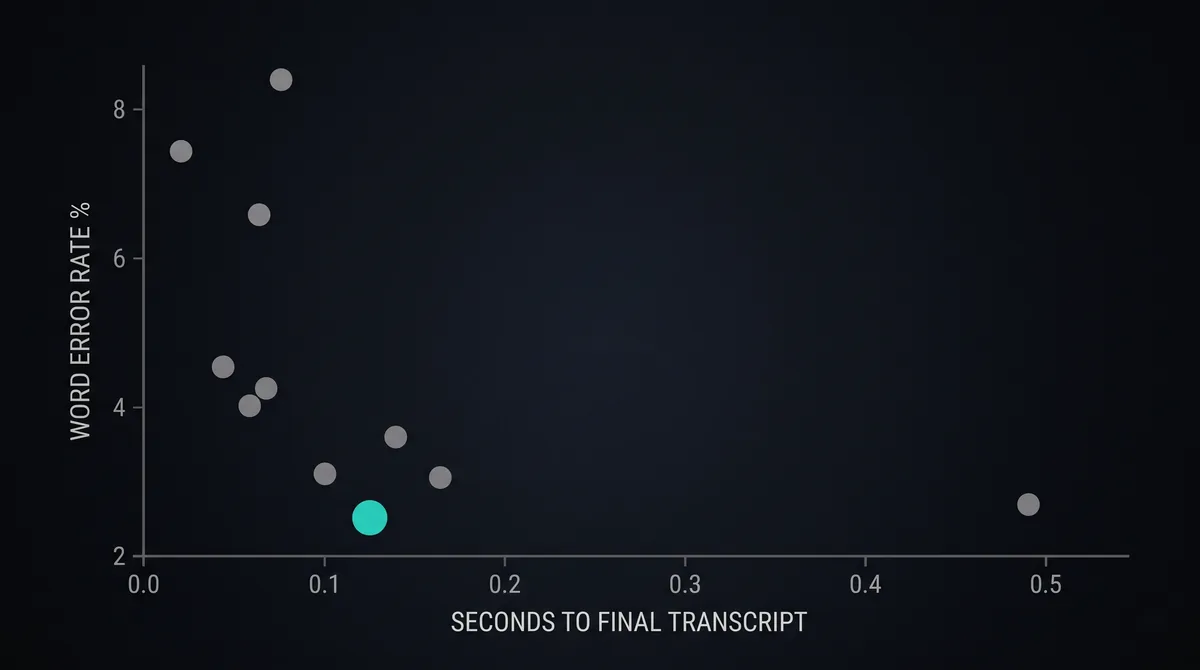
Microsoft calls its new streaming speech model accurate, fast and low cost. Two of those verify at no. 1 of 38 on the board it cites. On price it is 29th.
A distillation scaling paper predicts peak accuracy to within 0.7 of a point at held-out scales. Its own appendices record three other quantities it could not fit. Counting what it claims against what it delivers.
An 18-page audit of nine AI assistants found 27 cases of conversation data reaching third-party trackers. One product holds 14 of them. Reading the tables instead of the abstract.
Google’s TTS launch post says infinite voices. The developer docs say 200 per project. Four places where the announcement and the documentation diverge.