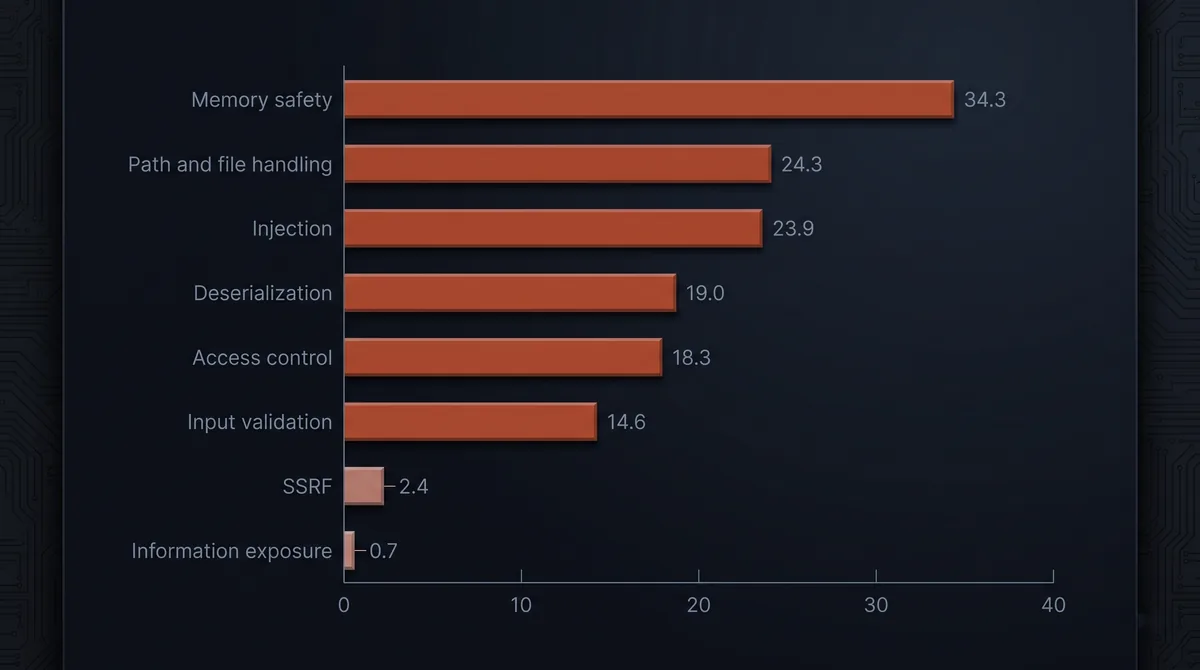
Three Fixes Work, Two Do Not, and SSRF Stays at 2.4%
An agent benchmark where the top performer on functional tests wrote the least secure code. Three interventions measurably help, two do not, and two weakness families stay near zero throughout.
An agent benchmark where the top performer on functional tests wrote the least secure code. Three interventions measurably help, two do not, and two weakness families stay near zero throughout.
A new benchmark had AI agents write reusable static-analysis checkers. 78.25% compiled, 73.65% told the broken revision from the fixed one, 32.30% were accepted. The loss is almost entirely after detection, and the two obvious explanations both test small.